B5 Batch independent trajectories on one GPU
Eight copies of a 64-atom cell with different seeded velocities stay eight
independent simulations, not one coupled 512-atom cell. Batch.from_data_list
lets one ALCHEMI run advance them together.
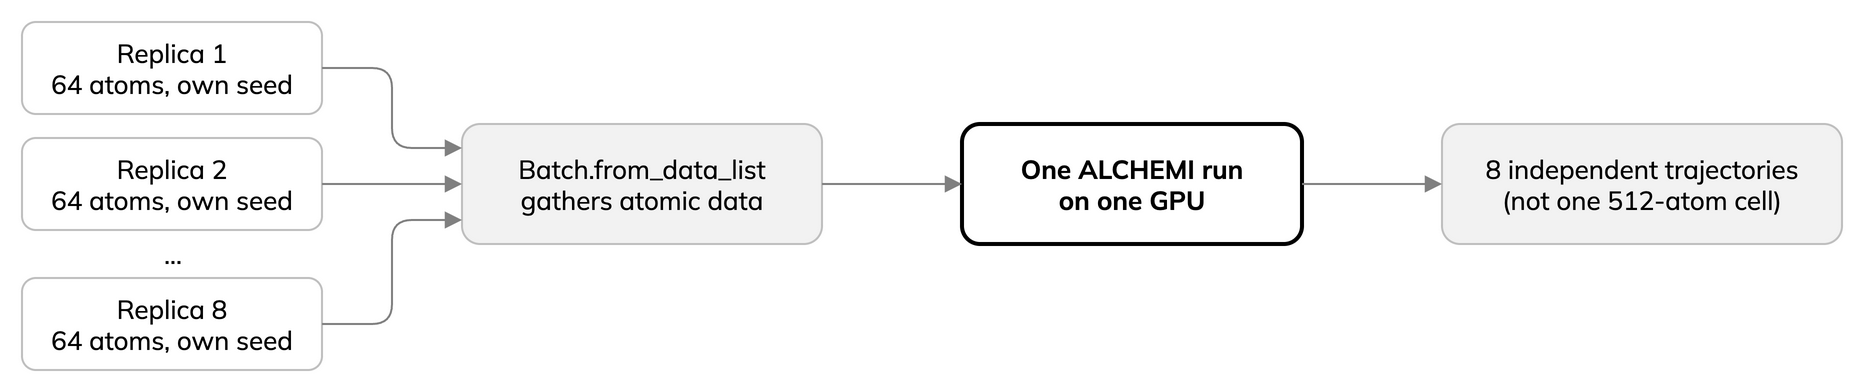
The cells below time one trajectory, then eight, on the same GPU. Do not run another GPU notebook meanwhile. Terminal equivalent, from the lesson checkout:
bash scripts/run-alchemi.sh --replicas 1 --cells 2 --integrator nve --warmup 10 --steps 200
bash scripts/run-alchemi.sh --replicas 8 --cells 2 --integrator nve --warmup 10 --steps 200
The notebook times each whole command, including setup and model loading. The runner’s MD-only time is a different timing window.
The rows do different work, so their times are not a speedup ratio.
For methods on the same eight simulations, see the B7 reviewed results; these short live runs only illustrate.
Aggregate rate:
simulations × measured steps / time to finish all(MD steps per second across all simulations, not per trajectory).Larger systems may already fill the GPU, so batching gains less.
Note
For NVT, change --integrator nve to langevin in both cells. ALCHEMI uses
NVTLangevin; native LAMMPS can use langevin with nve/kk or a Nose–Hoover
nvt/kk fix. Same target temperature does not make these interchangeable;
keep NVE and NVT results in separate tables.