B6 Run the same silicon case with LAMMPS
LAMMPS loads the validated ML-IAP export of the MACE checkpoint; ML-IAP connects the potential and
/kkstyles run supported GPU work with Kokkos.Activation uses the LAMMPS Python library, not yet a standalone
.inrecipe.Input below; complete source supplied.
lammps_si.py
32        for command in (
33            "package kokkos newton on neigh half",
34            "units metal", "atom_style atomic/kk", "newton on", "boundary p p p",
35            f"region box block 0 {length} 0 {length} 0 {length}",
36            "create_box 1 box", "run_style verlet/kk", "mass 1 28.085",
37        ):
38            lmp.command(command)
39        if count == 64:
40            for position in np.asarray(atoms.positions):
41                lmp.command("create_atoms 1 single " + " ".join(f"{v:.17g}" for v in position) + " units box")
42        else:
43            positions = np.asarray(atoms.positions, dtype=np.float64).reshape(-1).tolist()
44            created = lmp.create_atoms(count, None, [1] * count, positions)
45            if created != count:
46                raise RuntimeError("LAMMPS bulk atom creation failed")
47        if lmp.get_natoms() != count:
48            raise RuntimeError("LAMMPS atom count mismatch")
49        for command in (
50            f"atom_modify sort {atom_sort_interval} 0.0",
51            f"pair_style mliap/kk unified {model} 0",
52            "pair_coeff * * Si",
53            f"velocity all create 300 {seed} mom yes rot yes dist gaussian",
54            "timestep 0.0001",  # LAMMPS metal time is ps: 0.1 fs
55            "fix integrate all nve/kk",
56        ):
57            lmp.command(command)
58        if integrator == "langevin":
59            lmp.command(f"fix bath all langevin 300 300 0.1 {seed + 1}")
60        lmp.command("run 0")
With the MPI-enabled native runtime extracted and set as MLIP_NATIVE_PREFIX,
the first cell runs one 64-atom NVE trajectory on one GPU (one rank, not an
MPI scaling test). Terminal equivalent, from the lesson checkout:
bash scripts/run-lammps.sh --replicas 1 --cells 2 --integrator nve --warmup 10 --steps 200
As with ALCHEMI, the notebook times the complete command; the runner’s MD-only time is shown separately.
Eight independent simulations on one GPU, three workloads:
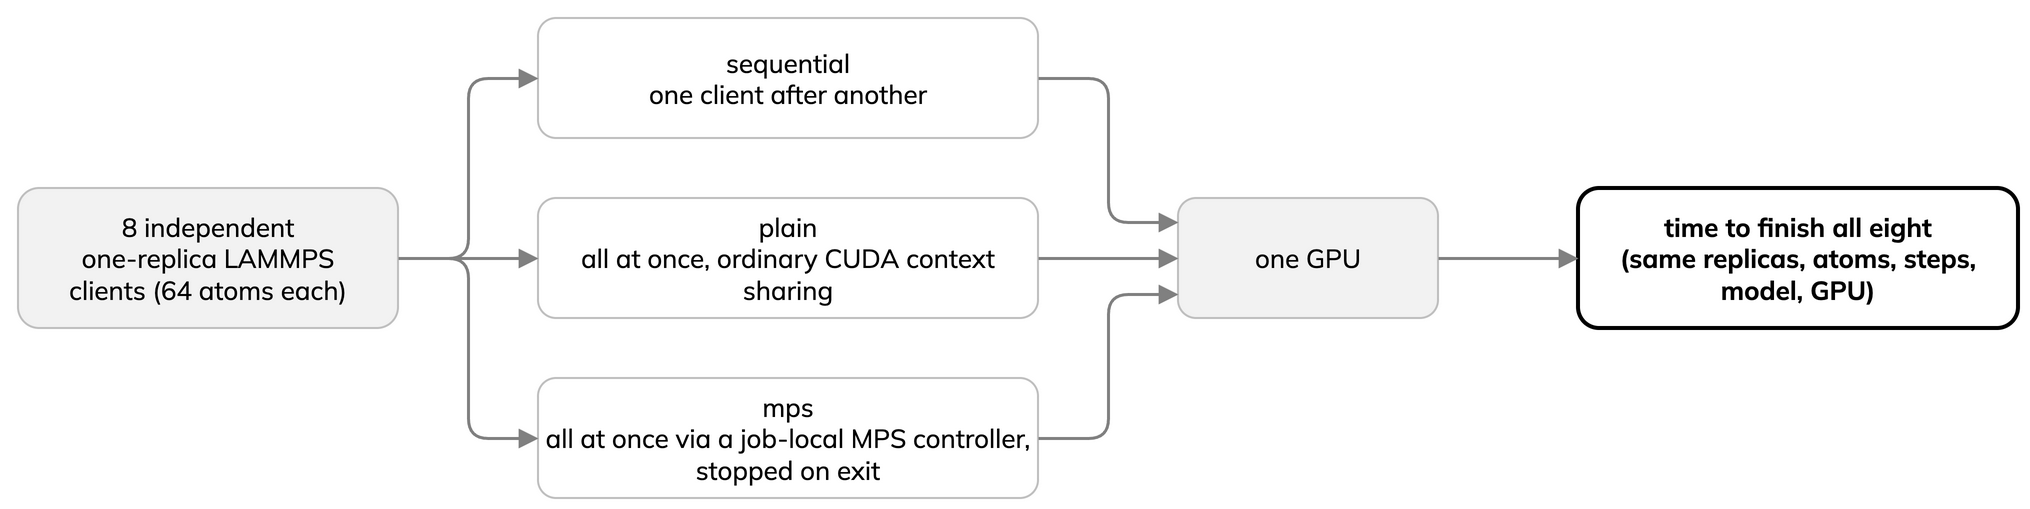
sequential: one client after another. Baseline; no concurrent sharing.plain: all eight at once; ordinary CUDA context sharing.mps: job-local CUDA Multi-Process Service (MPS) controller with private pipe and log directories, confined to the allocation and stopped on exit. May cut context-scheduling overhead; no guaranteed speedup.
ALCHEMI’s single-process
Batchis none of these modes.Metric: time to finish all eight, with the same replicas, atoms, steps, model and GPU.
B7 reviewed results keeps plain and MPS in separate rows.
Optional, longer cells: run each once in a suitably long allocation, not alongside another GPU exercise.
Terminal equivalents, run individually from the lesson checkout:
bash scripts/run-lammps-group.sh sequential --cells 2 --integrator nve --warmup 10 --steps 200
bash scripts/run-lammps-group.sh plain --cells 2 --integrator nve --warmup 10 --steps 200
bash scripts/run-lammps-group.sh mps --cells 2 --integrator nve --warmup 10 --steps 200
Each cell times its complete command, including wrapper startup. The
runner’s group_wall_seconds starts later and is not used for this
comparison.