JUPITER setup: native LAMMPS and ALCHEMI
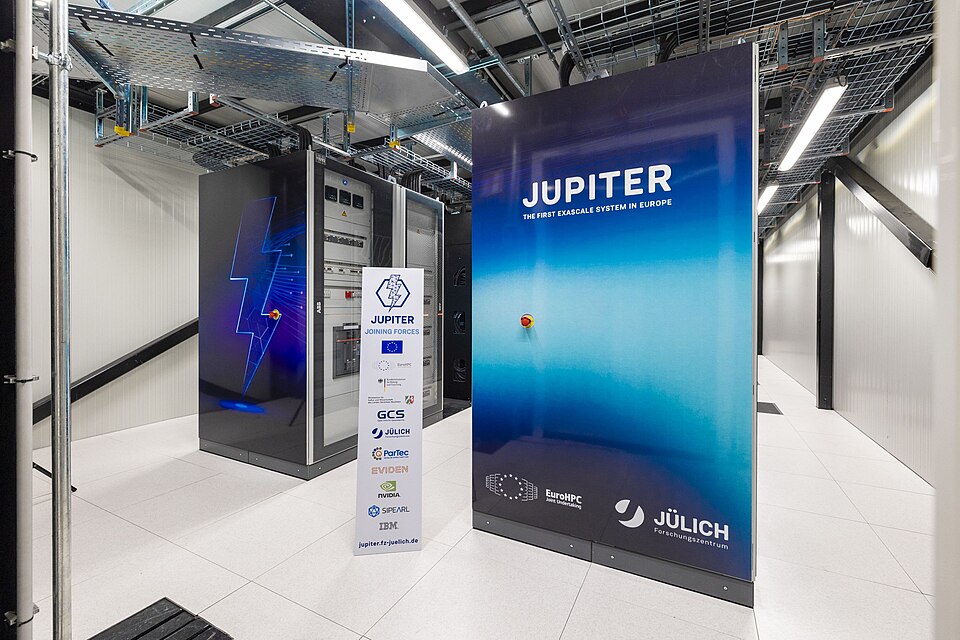
JUPITER Booster racks. Photo: Forschungszentrum Jülich / Sascha Kreklau; source and license details (CC BY 4.0). This copy was resized; the photo does not imply institutional endorsement.

Note
JUPITER hardware According to the JUPITER Booster configuration, each booster node has four GH200 superchips; each combines a 72-core Arm CPU with a GPU with 96 GB of high-bandwidth memory.
This profile has passed short one-, two-, four-, and eight-GPU silicon runs with the pinned MACE ML-IAP export; the eight-GPU run used two nodes. These are functional checks, not throughput or scientific-equivalence benchmarks. Both cells in B5 completed through a private Jupyter kernel. A short private JupyterLab server passed TLS-fingerprint and authenticated-API checks, then its allocation was cancelled. Do not use an Arrhenius SIF or MPI binary here. Native ALCHEMI has separately passed one-GPU, one- and eight-trajectory five-step NVE smokes. Neither smoke is a throughput benchmark.
The tested native module family is:
module purge
module load Stages/2025 GCC/13.3.0 CMake/3.29.3 CUDA/12 \
  OpenMPI/5.0.5 Python/3.12.3 PyTorch/2.5.1
Use a private project directory outside the lesson Git repository, for
example /e/project1/<PROJECT>/<USER>/mlip-hands-on. Put the pinned LAMMPS
source archive and model in its inputs/ directory; check their hashes in
reference/model.toml and the build script. Set MLIP_JUPITER_ROOT to that
private directory. The candidate builder verifies the source archive, then
builds OpenMPI, CUDA/Hopper Kokkos, ML-IAP, and a shared LAMMPS library:
export MLIP_JUPITER_ROOT=/e/project1/<PROJECT>/<USER>/mlip-hands-on
sbatch --account=<PROJECT> scripts/build-jupiter-lammps-mpi.sbatch
Do not repeat a submission if its outcome is uncertain. Check the job and the candidate directory first. A completed build is not yet a run. Package its Python wrapper from the same pinned source and shared library:
export MLIP_JUPITER_BUILD_ID=<completed-build-job-id>
bash scripts/package-jupiter-lammps-python.sh
The wrapper goes into a private Python environment; the script never
installs it into the site modules. That environment needs the MACE checkpoint
dependencies and cuequivariance plus cuequivariance-torch 0.11.1 for the
validated ML-IAP export. The latter two versions match the tested exporter
environment. A working import lammps alone does not establish a GPU run.
JUPITER’s batch shell can see all four GPUs even when the job requested
one. The tested one-GPU script runs its Python calculation inside
srun --gpus=1, where PyTorch sees one device. Do not replace that step with
a direct batch-shell Python call when testing this lesson’s one-GPU code.
The pinned original checkpoint did not export locally with the first JUPITER MACE environment: its conversion failed while loading symmetric-contraction weights. The one-GPU runtime check instead used an independently hashed ML-IAP export made from the same checkpoint. Recheck the export recipe before teaching local export as a completed JUPITER step. The source and runtime must remain two separate claims.
For a short check of that exact export, put it in the private inputs/
directory as mace-mliap-db578c55.pt, stage this repository outside the
allocation, and submit the smoke script with both paths in the Slurm
environment:
export MLIP_LESSON_ROOT=/path/to/staged/mlip-hands-on
sbatch --account=<PROJECT> --export=ALL,MLIP_JUPITER_ROOT,MLIP_LESSON_ROOT,MLIP_JUPITER_BUILD_ID \
  scripts/test-jupiter-lammps-verified.sbatch
The smoke runs 64 silicon atoms for five measured NVE steps. It checks that LAMMPS, ML-IAP/Kokkos, the wrapper, model and GPU step execute together; it does not measure throughput or establish scientific agreement. Do not submit it until the private export has been verified against the hash in the script.
For one coupled 512-atom trajectory, the MPI script uses a distinct Slurm GPU
binding on each rank. JUPITER’s documented job examples request both --gres
and --gpus-per-task=1; each rank then sees its own GPU as device zero.
The shared-visibility mode used on Arrhenius is not selected here. For example,
the one-node four-GPU functional check is:
sbatch --account=<PROJECT> --nodes=1 --ntasks=4 \
  --gres=gpu:4 --gpus-per-task=1 --cpus-per-task=8 \
  --mem=256G --time=00:15:00 \
  --export=ALL,MLIP_JUPITER_ROOT,MLIP_LESSON_ROOT,MLIP_JUPITER_BUILD_ID \
  scripts/test-jupiter-lammps-mpi.sbatch
The same script accepts one node with one or two ranks, or two nodes with
eight ranks (four per node). Change the --nodes, --ntasks, --gres, and
--ntasks-per-node requests together; --gres=gpu:4 is per node for the
two-node case. It runs ten measured NVE steps, writes one private result per
rank, and verifies completion. On this system a partial-GPU request can still
allocate an exclusive whole node, so do not read the requested GPU count as
the billed allocation. Inspect current policy and queue before submitting.
The tested one-node two- and four-GPU and two-node eight-GPU runs completed. At 512 atoms and ten measured steps, rank-wise final energies were internally identical within each job but differed slightly across rank counts. These checks do not establish decomposition-independent scientific agreement or useful scaling.
Native ALCHEMI without the container group
JUPITER compute nodes have no outbound internet. Download the pinned Python
packages from a login node into a private wheelhouse; the locked build and
runtime requirements are in locks/. The download helper checks both lock
hashes and does not install packages:
export MLIP_LESSON_ROOT=/path/to/staged/mlip-hands-on
export MLIP_WHEELHOUSE_OUTPUT=/e/project1/<PROJECT>/<USER>/mlip-hands-on/alchemi-wheels.tar
bash scripts/prepare-jupiter-wheelhouse.sh
sha256sum "$MLIP_WHEELHOUSE_OUTPUT"
Record the resulting SHA-256 and use that exact archive for an offline, fresh virtual environment on a booster node. Do not put the wheelhouse, logs, or environment in Git. The script verifies the archive and both locks before installation; it does not replace a working environment:
export MLIP_JUPITER_WHEELHOUSE="$MLIP_WHEELHOUSE_OUTPUT"
export MLIP_JUPITER_WHEELHOUSE_SHA256=<reviewed-archive-sha256>
sbatch --account=<PROJECT> \
  --export=ALL,MLIP_JUPITER_ROOT,MLIP_LESSON_ROOT,MLIP_JUPITER_WHEELHOUSE,MLIP_JUPITER_WHEELHOUSE_SHA256 \
  scripts/prepare-jupiter-alchemi-env.sbatch
After that job completes successfully, set MLIP_JUPITER_ALCHEMI_ENV_ID to
its job ID. Put the original MACE checkpoint named in
reference/model.toml in the private inputs/ directory. A short GPU check
uses the same silicon trajectory as the Arrhenius example:
export MLIP_JUPITER_ALCHEMI_ENV_ID=<completed-environment-job-id>
export MLIP_JUPITER_REPLICAS=1
sbatch --account=<PROJECT> \
  --export=ALL,MLIP_JUPITER_ROOT,MLIP_LESSON_ROOT,MLIP_JUPITER_ALCHEMI_ENV_ID,MLIP_JUPITER_REPLICAS \
  scripts/test-jupiter-alchemi.sbatch
Set MLIP_JUPITER_REPLICAS=8 for the separate batched functional check.
Both replica counts completed on one GPU with the pinned checkpoint. The smoke
script refuses other replica counts; adjust it only after reviewing a new
test. These checks prove that the pinned native environment, GPU, model, and
short trajectories work together. They do not establish comparative speed,
temperature equilibration, or scientific agreement with LAMMPS.
The same scripts/run-alchemi.sh used by the MyST notebook cells accepts an
explicit native mode on JUPITER. In an allocated GPU step, set:
export MLIP_ALCHEMI_RUNNER=native
export MLIP_NATIVE_ALCHEMI_PYTHON="$MLIP_JUPITER_ROOT/env-alchemi-$MLIP_JUPITER_ALCHEMI_ENV_ID/bin/python"
export MLIP_MODEL="$MLIP_JUPITER_ROOT/inputs/mace-mp-0a-small-2ddb079cee0e131e.model"
The eight-replica short smoke and both cells in B5
passed through that exact runner. Launch
the notebook only inside a GPU-bound srun step so the kernel sees one GPU.
For a private JupyterLab environment, build the course’s patched MyST wheel
as described in jupyterlab-enccs/README.md
and stage it under the private root. The preparation script checks the exact
wheel identity, then installs Jupytext and Matplotlib alongside the site’s
JupyterLab 4.3.4 in a fresh private environment:
export MLIP_JUPITER_MYST_WHEEL="$MLIP_JUPITER_ROOT/inputs/jupyterlab_myst-2.4.2-py3-none-any.whl"
export MLIP_JUPITER_MYST_WHEEL_SHA256=<reviewed-wheel-sha256>
export MLIP_JUPITER_JUPYTER_ENV="$MLIP_JUPITER_ROOT/jupyter-env-course"
bash scripts/prepare-jupiter-jupyter-env.sh
After reviewing the private environment and source lesson, submit one bounded
GPU notebook session. The direct Slurm form below requires MLIP_JUPITER_ROOT
to be owner-only because it stores a token-bearing log there. The %j
placeholder is replaced by Slurm with the job ID:
sbatch --account=<PROJECT> \
  --output="$MLIP_JUPITER_ROOT/jupyter-%j.log" \
  --error="$MLIP_JUPITER_ROOT/jupyter-%j.err" \
  --export=ALL,MLIP_JUPITER_ROOT,MLIP_LESSON_ROOT,MLIP_JUPITER_ALCHEMI_ENV_ID,MLIP_JUPITER_JUPYTER_ENV \
  scripts/jupiter-jupyter.sbatch
The preferred helper keeps logs in their own owner-only directory, validates the environment paths, and prints the one job ID without showing the token:
export MLIP_ACCOUNT=<PROJECT>
export MLIP_JOB_LOG_DIR="$MLIP_JUPITER_ROOT/private-jupyter-logs"
bash scripts/submit-jupiter-jupyter.sh
From your laptop, use the notebook mode of scripts/connect-from-laptop.sh
with your JUPITER SSH alias and job ID to verify the private TLS fingerprint
and forward the notebook.
Cancel the allocation when finished; closing the browser does not stop Slurm.
Metatomic MACE in native LAMMPS/Kokkos
This is a separate LAMMPS pair style from the ML-IAP route above. The pinned Metatomic fork needed a four-file compatibility patch: two Kokkos classes still declared a device-picker override removed from their base classes. The patch removes only those stale declarations and dead definitions; it does not change the force calculation. Keep the original checkpoint, exported Metatomic model, package overlays, and LAMMPS build outside Git.
On a login node, prepare the pinned fork and private Python overlays:
export MLIP_LESSON_ROOT=/path/to/staged/mlip-hands-on
export MLIP_METATOMIC_SOURCE="$MLIP_JUPITER_ROOT/lammps-metatomic-patched-6a3910424d0aeccf27ad1fc233be1933f72631d2"
export MLIP_METATOMIC_OVERLAY="$MLIP_JUPITER_ROOT/metatomic-overlay-course"
export MLIP_MACE_EXPORT_OVERLAY="$MLIP_JUPITER_ROOT/mace-export-overlay-course"
bash scripts/prepare-jupiter-metatomic-source.sh
bash scripts/prepare-jupiter-metatomic-env.sh
The exporter uses the pinned original MACE checkpoint, zero training epochs, and a tiny dummy silicon structure to make a Metatomic-format model. The dummy structure supplies the export interface; it is not training data for a new potential. Record the printed SHA-256 of the fresh export instead of assuming exports are byte-identical:
export MLIP_MACE_MODEL="$MLIP_JUPITER_ROOT/inputs/mace-mp-0a-small-2ddb079cee0e131e.model"
export MLIP_METATOMIC_EXPORT_DIR="$MLIP_JUPITER_ROOT/metatomic-export-course"
bash scripts/export-jupiter-metatomic-model.sh
Build the MPI/CUDA/Hopper LAMMPS executable on one booster node. The script checks the four patched source hashes and links against the NCCL bundled with the pinned PyTorch environment, rather than an older site NCCL:
sbatch --account=<PROJECT> \
  --export=ALL,MLIP_JUPITER_ROOT,MLIP_METATOMIC_SOURCE,MLIP_METATOMIC_OVERLAY,MLIP_JUPITER_ALCHEMI_ENV_ID \
  scripts/build-jupiter-metatomic-mpi.sbatch
Set MLIP_JUPITER_METATOMIC_BUILD_ID to the completed build job ID,
MLIP_METATOMIC_MODEL to the private exported model.pt, and
MLIP_METATOMIC_MODEL_SHA256 to its recorded hash. The smoke script checks
all three identities. Its default input is a 64-atom silicon NVE trajectory;
for multi-GPU runs, set MLIP_METATOMIC_INPUT to the staged
examples/lammps_metatomic_si_512.in instead. The default 64-atom input is:
 1# Short silicon NVE smoke with an exported Metatomic MACE model.
 2# Supply the private model path as: -var model /path/to/model.pt
 3package kokkos newton on neigh half
 4units metal
 5atom_style atomic/kk
 6boundary p p p
 7
 8lattice diamond 5.43
 9region box block 0 2 0 2 0 2 units lattice
10create_box 1 box
11create_atoms 1 box
12mass 1 28.085
13
14pair_style metatomic/kk ${model}
15pair_coeff * * 14
16timestep 0.0001
17velocity all create 300.0 37214 mom yes rot yes dist gaussian
18fix integrate all nve/kk
19thermo_style custom step temp pe ke etotal
20thermo 1
21run_style verlet/kk
22run 5
The complete 64-atom input is shown
above; the 512-atom input changes
the diamond-lattice box from 0 2 to 0 4 in each direction. units metal
makes the timestep unit picoseconds, so 0.0001 is 0.1 fs. pair_style
loads the exported model passed as ${model}, while pair_coeff * * 14
maps the one atom type to silicon’s atomic number. The nve/kk fix
integrates without a thermostat; thermo 1 prints diagnostic quantities
each step, and run 5 advances only five steps. The job script supplies
the model variable and launches the MPI ranks with srun. In isolation,
the corresponding LAMMPS command is:
lmp -k on g 1 -sf kk -var model "$MLIP_METATOMIC_MODEL" \
  -in "$MLIP_METATOMIC_INPUT"
That line is an explanation of the input interface, not a replacement for the validated Slurm job: its GPU count and rank binding come from the allocation. Opening this notebook does not submit it.
A two-GPU job request, to issue manually after checking the site policy, is:
export MLIP_METATOMIC_INPUT="$MLIP_LESSON_ROOT/examples/lammps_metatomic_si_512.in"
sbatch --account=<PROJECT> --nodes=1 --ntasks=2 --ntasks-per-node=2 \
  --gres=gpu:2 --gpus-per-task=1 --cpus-per-task=8 --mem=128G \
  --export=ALL,MLIP_JUPITER_ROOT,MLIP_LESSON_ROOT,MLIP_JUPITER_METATOMIC_BUILD_ID,MLIP_METATOMIC_MODEL,MLIP_METATOMIC_MODEL_SHA256,MLIP_METATOMIC_OVERLAY,MLIP_JUPITER_ALCHEMI_ENV_ID,MLIP_METATOMIC_INPUT \
  scripts/test-jupiter-metatomic-mpi.sbatch
One, two, and four GPUs on one node and eight GPUs across two nodes passed short functional runs with this Metatomic fork. For four GPUs, request four ranks and four GPUs on one node. For eight, request two nodes, four ranks and four GPUs per node, and eight total ranks. These five-step smokes do not measure scaling, establish cross-engine force agreement, or prove a long trajectory stable. The earlier ML-IAP/Kokkos path remains the reviewed performance baseline until a separate matched benchmark is completed.
The container-group route is intentionally omitted from this profile.
Neither native LAMMPS nor this native ALCHEMI environment needs that group.